
Crawling is the process of search and AI bots fetching, or attempting to fetch, content and other information from URLs.
SEO is no longer just for Googlebot. This post is part of a series on adapting technical SEO for AI bots and new search behaviors. Explore the full series.
Robots from search engines and AI systems need to crawl through your website’s pages, images, videos, and other content. Allowing access and supporting bot crawl activity is the most fundamental level of technical SEO and technical GEO. If robots cannot crawl your website successfully, then your website cannot rank in search results or be cited in AI responses.
How do Google and other bots crawl websites?
Google has been the most transparent and detailed about how its bots crawl websites. Broadly speaking, all bots follow these same basic processes.
- Discoverability. Before robots can crawl a website, robots need to discover the URLs contained on the website. Robots discover new pages primarily through links, including external links from other websites and internal links within your website. This is why updating your website’s navigation and avoiding orphan URLs is so critical. Pages can also be discovered from your website’s XML sitemap.
- Fetching. After discovering a URL, Google queues up the page for crawling. You need to make sure that the page can be crawled and is not blocked from crawling by the robots.txt file. If the page can be crawled, Google will send its crawlers to your website to fetch the page’s content. Along with fetching the page contents, Google will also check the page’s status code and the HTTP headers.
- Rendering. After fetching the page’s content, Google will queue the page up for rendering. This is where Google executes any JavaScript code needed to view the page’s content. You need to make sure Google can access those JavaScript files. Google renders pages using a headless version of Chrome, so you can set up a headless browser to test what Googlebot sees. Once rendered, Google will process the URLs and determine how to index those URLs. Learn more about page rendering.
- Refresh. Google wants the latest version of every page. So, Google will return to the URLs it knows about frequently to check for any updates. The more important Google thinks a page is, the more Google will return to that page. However, even pages that don’t seem that important will be recrawled. For example, I regularly see Googlebot returning to redirected URLs or error URLs, even though those errors and redirects have been in place for years.
What bots are crawling my website?
Bots identify themselves by declaring a User Agent. A User Agent can be thought of as a name for a specific bot. The User Agent is passed to the server when a page is loaded. Keep in mind that bots are not required to declare a User Agent. A lot of spammy bots will not declare a User Agent. However, most reputable services sending bots to crawl websites will give their bots a name. Google, Bing, OpenAI, and other major AI platforms all declare a name for their bots.
Googlebot User Agents
You can view the full list of Google’s User Agents. Here are the most common user agents Google uses to crawl the web.
| User Agent | Description |
|---|---|
| Googlebot Smartphone | Primary search crawler for mobile |
| Googlebot Desktop | Primary search crawler for desktop |
| Googlebot-Image | Image search crawler |
| Googlebot-Video | Video search crawler |
| Google-InspectionTool | Crawler for Google’s testing products (Rich Results Test and Inspect URL in Google Search Console) |
Bing User Agent
Unlike Google, Bing does not differentiate the User Agent based on the type of content being crawled. Bing has other user agents for ads, but for SEO, the main User Agent is Bingbot.
OpenAI & Other AI User Agents
Some of the most common AI bots are listed in the following table, though this list is subject to change.
Broadly speaking, there are three different types of AI bots: training, search, and user interaction. For example, OpenAI has one bot for each purpose: OAI-SearchBot is used to find links for OpenAI’s search engine, GPTBot is used for training the model, and ChatGPT-User is used when ChatGPT crawls a website to answer a user’s prompt.
| User Agent | Company | Description |
|---|---|---|
| OAI-SearchBot | OpenAI | Crawler for search results |
| ChatGPT-User | OpenAI | User interactions |
| GPTBot | OpenAI | Collects training data for AI models, crawls at irregular intervals |
| Meta-ExternalAgent | Meta | Collects training data for Meta’s AI models |
| PerplexityBot | Perplexity | Crawler for search results |
| Perplexity‑User | Perplexity | User interactions |
| ClaudeBot | Anthropic | Collects training data for AI models |
| Claude-User | Anthropic | User interactions |
| Claude-SearchBot | Anthropic | Crawler for search results |
| CCBot | Common Crawl | Possible source for AI training data |
How to guide what bots crawl?
Bots are designed to be greedy by default and are biased towards crawling every discovered URL. (This is why URL discovery is crucial for SEO and GEO success.) This makes sense for search engines or AI services: the more content they have, the more they have to rank or use in generated responses.
However, greedy bots can become a problem. There are pages bots should not crawl (like staging websites or user account areas). There are pages where bots should not crawl frequently (like dynamic pages where excessive crawls could waste server resources or crash the site). With AI search, some pages should not be part of the training data (like protected or proprietary works). There are also pages you may want included as part of training data, but not part of Google’s rankings.
There are two common methods available to guide crawling behavior.
- Robots.txt: The robots.txt file is a plain text file that can provide instructions to robots. A disallow statement can be added to the website’s robots.txt file, telling bots not to crawl a specific page. For example, a disallow statement could tell OpenAI’s bots not to crawl your older blog posts. Google, Bing, OpenAI, Perplexity, and other reputable bots will obey the robots.txt instructions but the robots.txt instructions are optional. There are a couple of big things to remember when using a robots.txt disallow to manage and guide robots:
- First, Google may still index and rank a page it can’t crawl if links point to the page and sufficient signals suggest the page is useful.
- Second, never block CSS or JavaScript files because bots need those files to fully understand the site’s content.
- Requiring authentication: A stronger signal to guide bots is to restrict certain parts of the website behind a login (this is communicated with a 403 status code). Search bots do not fill out forms or interact with the page during a crawl. They also wouldn’t have the login information to use, even if they could complete the login form. As a result, bots would be unable to fetch content behind that login. This is especially useful for staging websites where it is important to keep bots out.
How do I manage bot crawl volume?
The robots.txt file (discussed in the previous section) can help manage crawl volume by blocking Google (or AI bots) from crawling specific directories or specific pages. For example, if Google is excessively crawling site search pages, it might make sense to block crawls to manage server capacity.
There are stronger methods available to manage crawl volume instead of the robots.txt file. Google supports the use of two status codes to help manage crawl levels and make crawling more efficient. OpenAI, Meta, and other AI tools have not made it clear if they support these methods.
- Not modified (304): A 304 response reduces bandwidth for unchanged resources. You can send back a 304 response status code when a bot requests a page. This tells the bot the file has not been updated since the last time it crawled.
- Too many requests (429): For emergencies, where a bot is crawling too much, the server can send back an error status code. A 5xx status code indicates a temporary problem with the server. A 429 status code specifically indicates there were too many requests being made. Seeing this, bots will typically slow the current crawl volume and return at a later point.
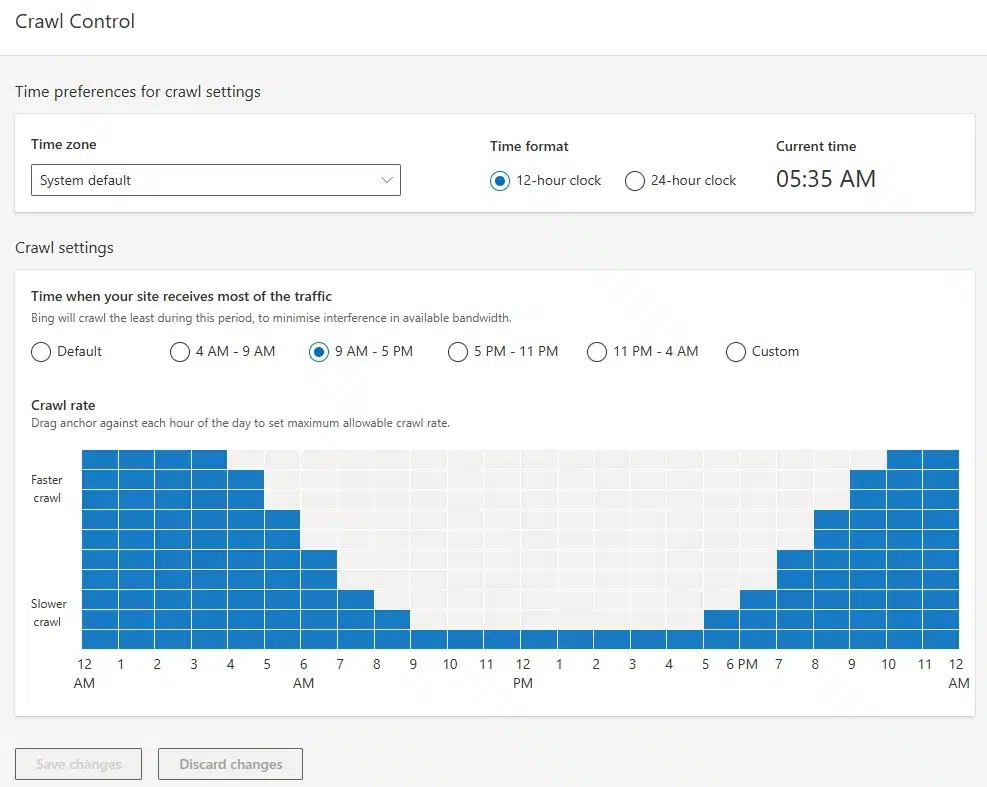
Bing offers another method to control crawling behavior. In Bing Webmaster Tools, under Configuration, you can access the Crawl Control settings. Bing allows you to set a time when Bing should crawl the least. This will prevent their bots from crawling the website during peak hours to avoid overloading the server.
How do I manage AI bot crawls in Cloudflare?
Bot access can also be managed in Cloudflare if your site is routed through their platform. Starting September 15, 2026, Cloudflare will block AI training bots by default, though this default setting can be changed.
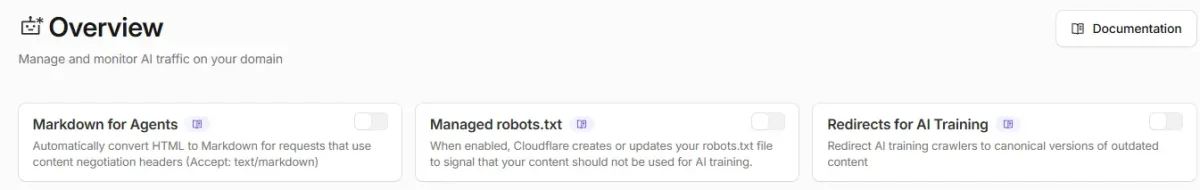
Cloudflare also allows for managing individual bots. From the main Overview page of your domain, you’ll find the AI Crawl Control section. In this section, you can decide whether to deliver Markdown for AI agents, allow Cloudflare to create a robots.txt file, and if you want to redirect AI training bots to training URLs.
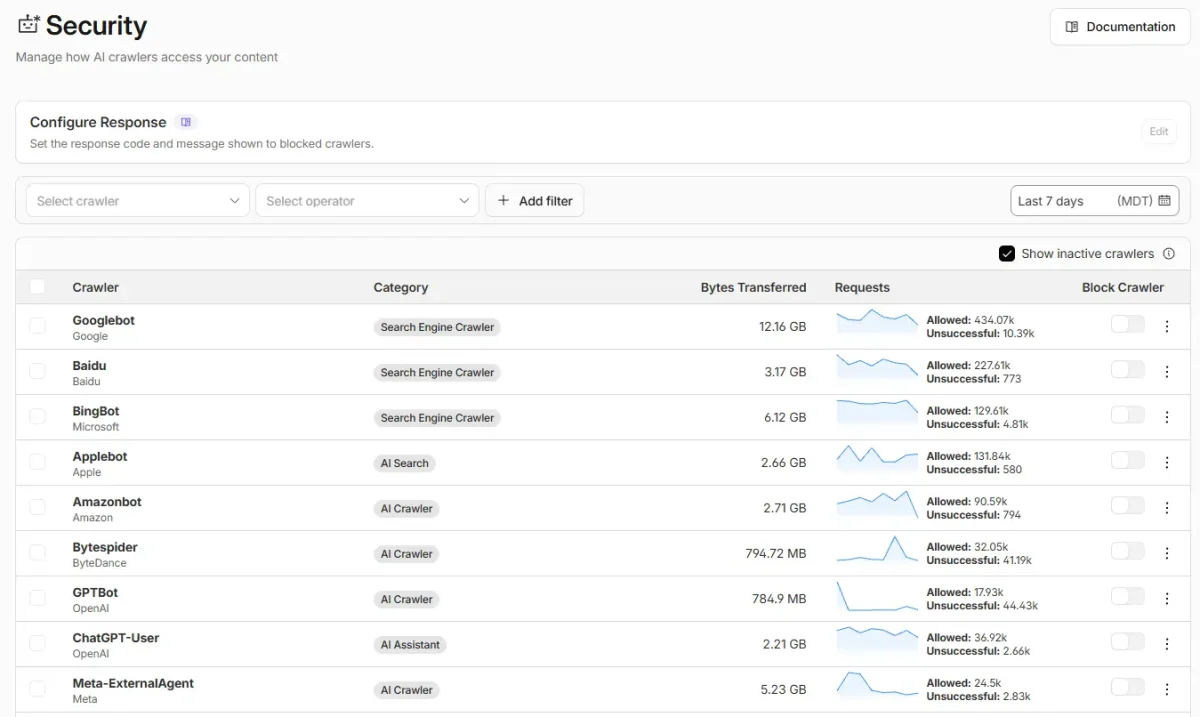
Cloudflare also offers the ability to control crawls for specific bots. In the sidebar, under AI Crawl Control, select Security. Here, you can see which bots are crawling your site, request trends, and how many requests from this bot were allowed versus unsuccessful. From the table, you can block specific bots instead of blocking all bots.
What affects a bot’s crawl efficiency?
Bots need to crawl the pages you want them to crawl as efficiently as possible.
At the most basic level, that means the server should be online. Server outages happen to all sites, but if they happen too often, that will prevent bots from crawling the website altogether. When server outages happen, the site should return a 503 status code to make it clear the outage is only temporary. See the following video for more information.
The server also needs to be capable of responding to a bot’s request for a page. Some servers are set to block unknown bots. This can especially impact new AI bots and prevent them from crawling the site altogether. Other servers limit how many URLs can be requested within a set time. This limitation can make it harder for bots to crawl pages.
After ensuring the server lets valid search and AI bots access the site, the next question is about website speed. The faster a website is, the easier it will be for bots to fetch content from the site’s pages. Focus especially on Time to First Byte (TTFB), which measures how long it takes the server to respond to a request. Per the latest recommendations, you ideally want to keep TTFB under 800 ms. Learn more about TTFB, Core Web Vitals and other key speed metrics.
Efficiency can also be gained by reducing low-quality content on the website. Bots don’t need to waste time crawling low-quality pages. That wastes server resources and causes problems later on when bots start indexing or training on the content found on low-quality pages.
Bots also don’t need to waste time crawling duplicate versions of pages. That includes URLs with query strings that do not change the page’s content, like tracking parameters. As with other types of low-quality pages, these URLs can waste bot and server resources. Preventing crawling of the parameters may help improve crawl efficiency.
How to monitor bot crawl activity?
The best way to monitor crawling is in the website’s log files. Log file data can help you answer several key questions to better understand how search and AI bots are using our websites. This includes answering questions like:
- Do robots use the website’s XML sitemap files?
- Which robots crawl the website and how frequently?
- Are robots crawling unnecessary pages (and, if so, how much)?
- How often do robots recrawl website pages?
- What errors do robots encounter? Are they accessing older content?
- Do training bots crawl different content than user interaction or search bots?
- Are robots respecting robots.txt rules you have configured?
Reviewing log data is the best way to spot crawl inefficiencies. For example, in reviewing log files, I have often spotted low-quality pages that are getting crawled excessively. I have also used log files to find important pages that are not being crawled as often as they should be, which indicates a problem might be preventing crawling.
Log files also show the status code the server used in response to the request. Pages that are operating correctly return a status 200. So, by reviewing pages that return non-200 status codes, you can find error pages that bots are crawling. That includes finding server errors (status codes will start with a 5).
Log File Alternative: Known Agents
If you cannot access log files on your server or if your hosting company does not provide log files, another option is Known Agents. This can be used through a WordPress plugin, though Known Agents offers other types of connectors. This tool reports on which pages are getting crawled by different search and AI bots, including bots from Google, Bing, OpenAI, Perplexity, and Meta. The data is not as robust as working with log files directly, but I have found it to be a very helpful log file alternative.
Google Search Console: Crawl Stats & Live Test
Google Search Console’s Crawl Stats report is another way to monitor crawling. This only shows crawls by Google’s bots and the data is sampled. However, it is a useful way to spot trends and identify problems. Also, Crawl Stats data tends to be fairly accurate and aligns with log file data (for more details about the accuracy of Crawl Stats, see my data comparing Crawl Stats to log file data).
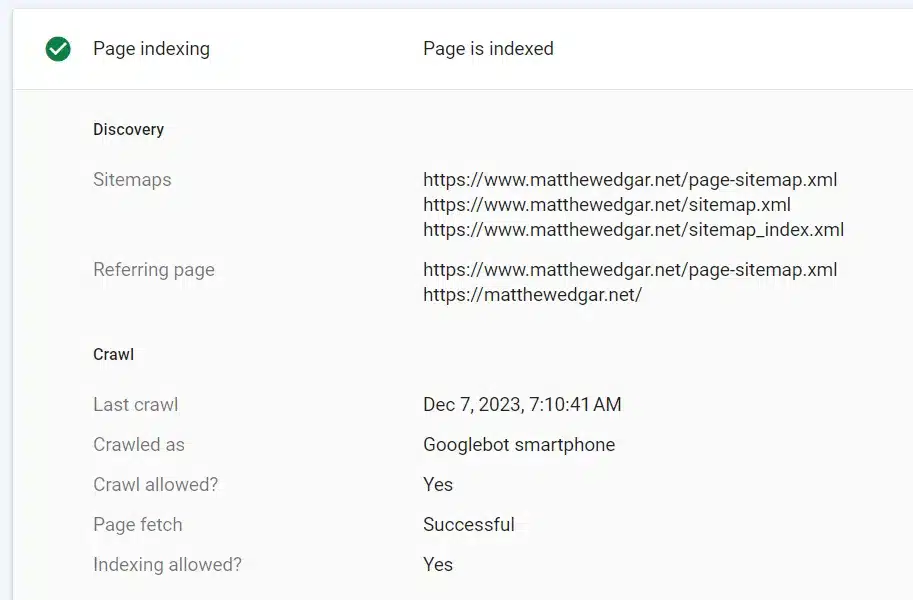
You can use the “Live Test” tool with URL Inspection in Google Search Console to see your website as Google. In Google Search Console, click on “URL Inspection”, enter the URL you want to test at the top of the screen, and then press enter.
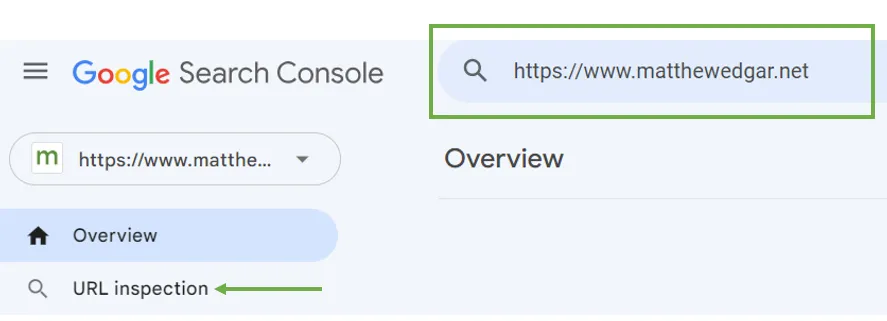
This will load the URL Inspection report. By default, this will show you information about the last time Google crawled this page. It will also provide information about how Google discovered this URL. However, in my experience, the Discovery information is not always reliable.
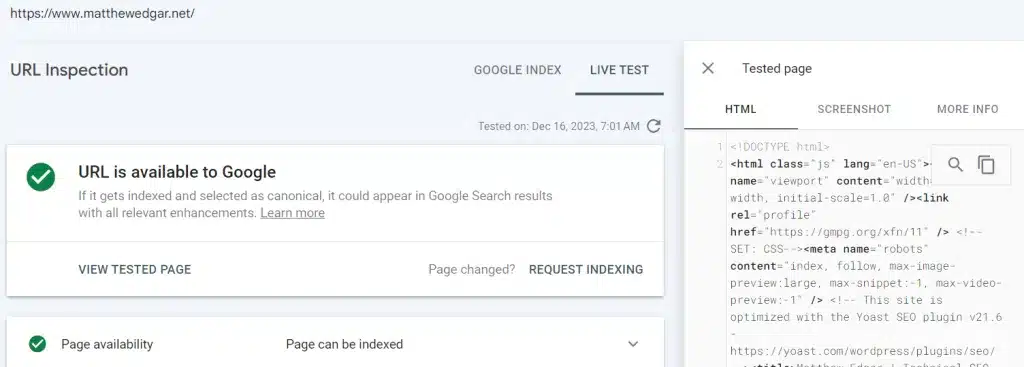
You can also Live Test the URL to test any recent changes. At the top of the screen, click “Test Live URL” in the upper right corner of this page. This will refresh the report with information about a fresh crawl.
On URL Inspection, you can also view more details about the tested page. Click the link that says “View Tested Page”. This will expand a panel showing what Google crawled. This includes the HTML crawled and a screenshot of the crawled page. The “More Info” tab shows the page headers, the page status code, and the resources Google had to fetch to render this page. This information can help you diagnose any issues with how Google has crawled the page.
Bing Webmaster Tools: Check Bing Crawlability
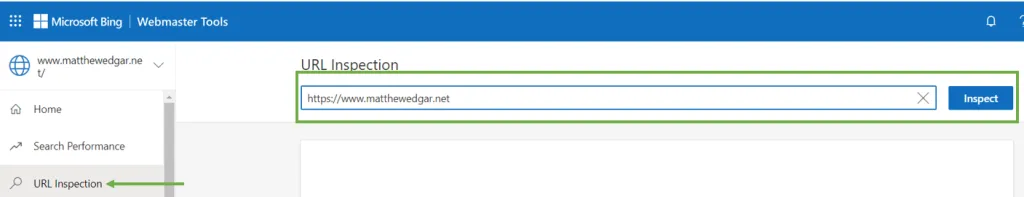
Bing also offers a URL Inspection report so you can confirm Bing can crawl this webpage. After logging into Bing Webmaster Tools, click on URL Inspection in the sidebar and then enter the URL you want to inspect.
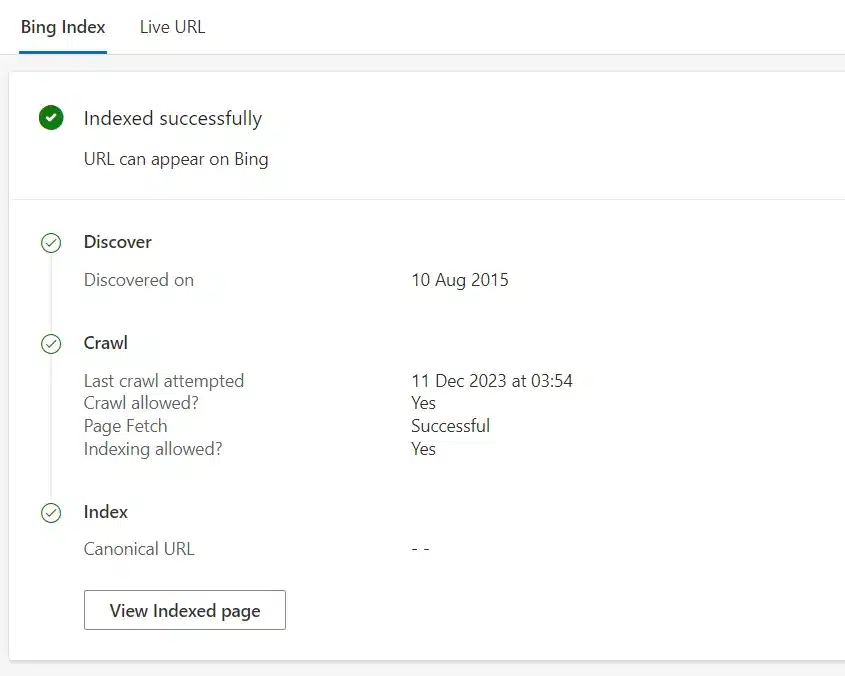
After inputting your URL in the search box, Bing will provide information about the last time this page was crawled. Bing also indicates when this page was discovered. You can click on “Live URL” to test crawls on the current state of the page.
Key Takeaways: Crawling
- Crawling is about more than Google’s bots. Crawling optimization should consider Google, Bing, OpenAI, and other AI bots.
- Determine which pages different bots should and should not crawl on your website. Set the guidelines and crawl limitations accordingly.
- Ensure bots can crawl sites as efficiently as possible. This includes not blocking bot requests, improving site speed, and reducing crawls of low-quality or garbage pages.
- Monitor bot crawling activity. Track which bots crawl, which pages are crawled, and any errors bots may encounter.
More on Modern Bot Behavior
This article is part of my series on how AI search is changing technical SEO and breaks down how we optimize for the six modern bot behaviors.
Read the next part: Rendering: How bots process your site’s code to “see” what’s on the page
Need help understanding how AI bots are crawling your website or want to optimize for AI search? Contact me and let’s talk.
More Articles
Schema Entity Mapping
Learn how to build an entity map, connect entities with schema markup and @id, and decide which information to repeat across your website.
Read Schema Entity Mapping →Schema: Find, Fix & Prevent Problems
Find and fix common schema markup problems, from invalid code to rendering issues. Learn how to audit and test schema with crawlers and validation tools.
Read Schema: Find, Fix & Prevent Problems →